Do Reddit upvotes affect AI search? Thread scores and citations (2026)
A median score of 12 on cited Reddit pages, plus the Signals order overlap. What the evidence supports before buying upvotes.
Originally published October 7, 2026
A higher Reddit score is not a measured shortcut to an AI recommendation. The median observed score was 12 among 11,681 scored Reddit pages in our cited sample. We also joined Signals vote-order targets to Parse's index and report the overlap, including the limits of the before-and-after coverage.
The thread-score study keeps the page sample and order ledger separate. The first describes scores on pages already cited; the second checks whether ordered threads appeared in the index. Neither is a randomized test of buying Reddit upvotes.
Signals runs an aged Reddit account marketplace plus an editorial network for AI brand mentions across Reddit, Quora, Product Hunt, and Threads.
Do Reddit upvotes affect AI search?
This batch does not establish that buying upvotes changes AI citation or brand naming. It establishes that the cited Reddit sample includes modest-score pages and that order targets have a measurable level of overlap with Parse's index. Those findings are useful precisely because they keep a visible score change separate from an AI outcome.
If the goal is an AI recommendation, begin with the answerable buyer question and the thread's relevance. A score is one attribute of the page. It does not tell us whether the discussion supplies accurate information about the product, whether the brand is mentioned, or whether the engine used that information.
The observed median of 12 is not a recommended target. We measured scores after pages entered the citation sample, with crawl times that differ from citation times. The study lacks an uncited-thread control population. It therefore cannot estimate how much another vote changes the chance of being cited.
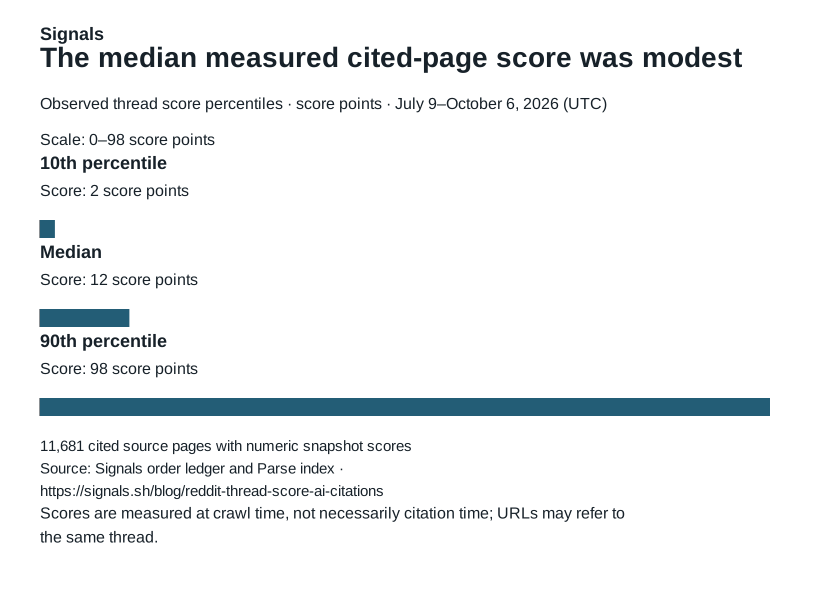
What does the cited-thread score distribution show?
The measured pages span low and high scores, with 1,106 pages at a score of at most one and 1,140 above one hundred. That range rejects the idea that every cited Reddit page must look viral. It does not show that low-score threads outperform high-score threads across Reddit as a whole.
The unit is a cited source page with a usable score in its latest available snapshot. Different URLs can refer to the same underlying discussion, and the source-page distribution is not a deduplicated census of all Reddit threads. We preserve that distinction in the figure labels and sample description.
Use the bands as a reason to read relevant discussions that might otherwise be dismissed. Inspect the actual answer, the product detail, and whether the thread remains usable. Do not discard a precise explanation because it lacks a large visible score, and do not approve an irrelevant discussion because its score looks impressive.
Does comment karma tell us which brand will be named?
The comment evidence suggests looking beyond a thread's headline score, but it does not identify a winning karma threshold. Parse detects brand mentions in comments and records aggregate engagement for matching comments. A sum across several comments is not the score of the particular sentence the engine may have used in an answer.
The Reddit comments study reports 79.4% comments-only page-brand pairs in its measured snapshot set. That tells us where the brand name was found on cited pages. It does not trace the model's reasoning or identify an individual comment as the cause of a recommendation.
For an operator, the practical review is textual. Check whether the comment explains a relevant use case, provides support for its claim, and discloses a commercial relationship when present. A count can help characterize the discussion, but it cannot substitute for those checks. Keep comment engagement and brand naming as different fields in the report.
What happened to the Signals order targets?
We normalized Reddit URLs to their thread identifiers and compared the eligible vote-order targets with Parse's citation-source index. Among 850 normalized upvote orders, 29 had a target found in the index. The result is an overlap measurement, not an estimate of the effect of the order or a claim about every AI engine.
The study also reports downvote targets and separates citation observations before and after placement where a placement timestamp exists. Current-engine history begins on May 24, 2026, so earlier orders do not have complete pre-order coverage in that panel. Missing history must not be interpreted as an observed zero baseline.
Orders can repeat the same thread, which is why the study exposes both orders and distinct targets. The normalized join also excludes malformed or unrecognized URLs. Customer identities and individual order URLs are not published. The aggregate result stands on its own, including any small or absent overlap with the monitored questions.
What do the starting and ending scores tell us?
Paired starting and ending scores show an observed change between recorded measurements for a subset of orders. They do not separate purchased delivery from organic votes, removals, display behavior, or the timing of measurement. We report those changes as ledger observations rather than treating them as verified incremental votes caused by the service.
The upvote subset with paired scores had a median change of 22.5 points. The study gives its sample size and reports downvote outcomes separately. A score comparison can be available even when the thread has no citation in the observed AI panel, so those denominators should never be merged casually.
For a campaign report, put delivery, visible score, traffic, and AI citations in separate columns. That makes it possible to see what was actually observed. If the score changed but no citation was recorded, report both facts. Replacing the missing AI result with the score result would answer a different question from the one the buyer asked.
When is an upvote proposal unsuitable for an AI objective?
It is unsuitable when the proposed evidence stops at the Reddit score while the promised result is an AI recommendation. We would reject that measurement gap before discussing quantity or timing. The study supports evaluating the thread's relevance and monitoring actual answers; it does not supply a conversion formula from ordered votes to citations.
Use these checks when reviewing a proposal:
| Check | Workable specification | Failed specification |
|---|---|---|
| Target | Exact relevant thread URL | A category or subreddit alone |
| Objective | Delivery and AI observation are separate | Score increase is called AI visibility |
| Baseline | Dated answers and source URLs are saved | Only an after screenshot exists |
| Reporting | Missing citations remain missing | Another metric replaces the promised result |
This is a review framework, not an endorsement of vote manipulation. Reddit's current rules and the community's requirements apply independently of the research. Do not assume a vendor's delivery claim makes an activity permitted or an AI benefit established.
What should a vendor specification say?
A concrete specification identifies the exact thread URL, the requested service, delivery timing, acceptance evidence, and the process for a failed or removed target. It also names the outcome being purchased. An execution service and an AI-visibility experiment are different scopes, and the buyer should not discover that distinction only after reviewing the report.
Ask the vendor to distinguish requested quantity, reported delivery, and observed score. If the goal includes AI research, define the question panel, engines, and observation dates separately. Require the complete source-bearing answer for any claimed citation rather than a screenshot showing only a brand name.
The DIY starting point is to improve the usefulness of the contribution and observe the existing thread before paying for execution. We cannot recommend a vote quantity, pace, or score threshold for AI citations from these data. The study has no design that identifies those parameters, so a specific prescription would go beyond what was measured.
How long after an order should citations change?
The ledger join cannot provide a dependable time-to-citation estimate. Many targets have limited or no overlap with the monitored source set, and orders can predate the current-engine history. Even when a citation appears after placement, that ordering alone does not show the order caused it or that the observed delay would repeat.
A proper lag study needs a reliable treatment time, a stable observation panel, enough follow-up, and a clear event definition. First citation, first brand naming, and first favorable recommendation are separate events. It also needs to address other changes to the thread and brand during the same window.
For the current work, save the placement timestamp and report the actual observed citation dates. Do not fill a missing result with a promised waiting period. Set an internal review schedule as a project-management choice and retain the original question panel so a later comparison measures the same thing as the baseline.
How should the next measurement be designed?
Choose the AI outcome before selecting an execution tactic. Fix the buyer questions, engines, target URLs, and observation window, then preserve a baseline. A stronger effect study would compare treated targets with credible untreated targets and account for topic, age, subreddit, and existing citation history instead of using only a before-and-after score difference.
The AI visibility guide gives the broader question-planning approach. Our score and ledger study records the current sample boundaries, including incomplete pre-order coverage and the difference between source pages, unique threads, and repeated orders.
Keep the report readable: what was delivered, what score was observed, whether the target was cited, and whether the brand was named. Each field should have its own denominator and timestamp. That format leaves room for a useful null result. It also prevents a delivery receipt from being presented as evidence for an unmeasured recommendation effect.
Questions operators ask before buying Reddit upvotes
The recurring questions focus on whether votes work, how many are needed, and whether results are guaranteed. For an AI-search objective, the available answer is narrower than a sales pitch: we can describe the scored cited pages and the order overlap, but we cannot turn either into a proven dose or guaranteed recommendation.
Does buying Reddit upvotes improve ChatGPT rankings?
This study does not establish that effect. It separates order delivery, score changes, citation overlap, and brand naming rather than treating them as equivalent results.
How many upvotes does a thread need to be cited?
No threshold was established. The sample contains already-cited pages and lacks the uncited comparison population needed to estimate citation probability by score.
Can an upvote vendor guarantee AI visibility?
No such guarantee follows from this research. Ask for the exact outcome, observation panel, evidence, and terms before evaluating the claim.